

Within the rapidly advancing field of artificial intelligence, generative AI has emerged as one of the most significant and transformative innovations of the 21st century. Defined by its ability to produce novel and sophisticated content that reflects human creativity and cognitive processes, generative AI is redefining the boundaries of machine intelligence across a wide range of applications (Krakowski, 2025; Budhwar et al., 2023). Unlike earlier, narrowly focused artificial intelligence systems, generative models synthesize original outputs spanning text, imagery, music, code, and scientific hypotheses, indicating a paradigm shift from mere automation to active co-creation and simulation (Sætra, 2023).
The advent of sophisticated generative models, such as GPT-4, DALL-E, and WaveNet, exemplifies this profound transformation (Sengar et al., 2024; Lv, 2023). By leveraging advanced architectures like transformers and generative adversarial networks (GANs), these systems learn intricate patterns from extensive datasets, producing outputs that are often indistinguishable from human-generated content (Hinz et al., 2016). Consequently, generative AI has opened remarkable opportunities across various sectors, including automated journalism, digital artistry, scientific research, and healthcare diagnostics. However, the widespread deployment of these powerful technologies has also introduced significant ethical, legal, and societal complexities. Issues surrounding authorship, misinformation, surveillance, algorithmic bias, and accountability have become increasingly critical as generative AI systems become integral to societal functions (Ferrara, 2024). Addressing these concerns effectively requires proactive engagement from ethicists, policymakers, technologists, and society at large.
The broader implications of generative AI fundamentally intersect with humanity's aspirational goals, including cognitive augmentation, societal advancement, and even interstellar exploration. The fusion of artificial and human intelligence raises profound philosophical questions about consciousness, identity, and the trajectory of civilization itself (Chowdhury et al., 2023). This evolving integration positions generative AI not merely as a tool but as a critical component shaping human cognitive and cultural evolution, necessitating interdisciplinary and anticipatory approaches.
Given these significant developments and their far-reaching implications, a comprehensive survey of generative AI is both timely and imperative. This paper makes five key scholarly contributions to the field of generative artificial intelligence (GenAI). First, it offers a holistic synthesis of the generative AI landscape by integrating technical, theoretical, and socio-ethical perspectives into a unified analytical framework. Second, it constructs a comprehensive historical narrative of text-based generative models, tracing their evolution from early probabilistic methods such as Markov chains to advanced transformer-based architectures like the GPT series. Third, it critically examines the socio-technical and ethical dimensions of GenAI, addressing pressing concerns such as misinformation, algorithmic bias, and accountability while advocating for responsible innovation. Fourth, it identifies significant research gaps and outlines emerging frontiers, including quantum-enhanced generative models, adaptive learning systems, and multi-modal integration. Fifth, it provides a balanced analysis of the political and economic dynamics of GenAI development, contrasting centralized proprietary models with decentralized open-source alternatives. Collectively, these five contributions advance scholarly understanding and inform future research, practice, and policy in the generative AI domain.
2. Methodology
This survey employs a systematic literature review approach to comprehensively synthesize existing research on generative AI. A thorough search was conducted using academic databases such as IEEE Xplore, ACM Digital Library, Science Direct, and Google Scholar, utilizing key terms including “generative AI,” “GPT models,” “transformers,” “GANs,” “quantum generative models,” “ethical implications of AI,” and “societal impacts of generative AI.” The search primarily focused on peer-reviewed journal articles, conference proceedings, technical reports, and authoritative reviews published between 2000 and 2024 to ensure relevance and comprehensiveness. We also included some references outside this timeframe to provide historical context for generative AI and key innovations.
The collected sources were rigorously screened for inclusion based on criteria such as relevance to generative AI development, technological significance, ethical considerations, and societal impacts. Publications were thematically categorized according to their contributions to historical perspectives, technological advancements, theoretical frameworks, ethical issues, and practical applications. This categorization enabled a structured analysis, highlighting key trends, gaps, and emerging directions within the field.
The synthesis was conducted using qualitative analysis techniques, employing thematic coding and narrative synthesis methods to integrate insights across diverse research areas. This approach facilitated the development of a coherent narrative that captures the evolution, current state, and future trajectory of generative AI. Additionally, expert opinions and forward-looking projections from influential studies were critically assessed to provide informed perspectives on future developments and anticipated challenges.
Table 1 presents the key concepts and topics in the generative field that are the focus of this paper, detailing their respective significance.
Table 1. A synoptic matrix of the paper's core contributions.
The structure of this paper is organized to guide readers comprehensively through the multifaceted domain of generative AI. Subsequent sections include detailed explorations of next-generation generative models, addressing emergent quantum and adaptive learning approaches; deep theoretical enhancements that elaborate on the foundational concepts underpinning these advancements; and cutting-edge research and uncharted territories that present innovative applications in fields such as nanotechnology, synthetic biology, and extraterrestrial simulations. The Societal Integration section critically analyzes the implications of generative AI for collaborative creativity, human-AI symbiosis, and governance. Meanwhile, the section on overcoming advanced challenges addresses transparency, robustness, and ethical alignment, proposing strategies to ensure the development of trustworthy systems. Finally, the Foreseeing the Future section speculates on generative AI’s broader impacts, particularly its potential roles in future exploration and infrastructure. By structuring the discussion this way, the paper provides a rigorous, holistic resource intended to support expert researchers, practitioners, and policymakers in navigating and shaping the transformative potential of generative AI. Table 2 presents a chronological timeline of key milestones in the development of text-based generative AI from 1906 to 2023. It highlights foundational breakthroughs such as the introduction of Markov chains, the emergence of early chatbots like ELIZA and PARRY, and the evolution of modern generative models including GPT, LaMDA, and open-source alternatives. This timeline illustrates the historical progression and technological convergence that have shaped the current landscape of generative AI.
3. History and background of text-based generative AI
The concept of generative text can be traced back to early 20th-century statistical models. One foundational technique was the Markov chain, introduced by Russian mathematician Andrey Markov in 1906 (Alalaq, 2024). A Markov chain predicts the probability of transitioning from one state (e.g., a letter or word) to the next based on observed frequencies, serving as an early method for generating text by chaining probable sequences. In the context of language, simple Markov models can generate text by selecting the next word based solely on the current word or a short history, effectively utilizing n-gram statistics. This approach demonstrated that machines could produce novel word sequences that mimic patterns in data, marking an early proof-of-concept for computer-generated text. However, classic Markov models lack long-term memory and cannot capture syntax or meaning beyond a few words of context. As a result, pure Markov-chain chatbots often produced incoherent or repetitive outputs. Nonetheless, these statistical models laid the groundwork for later generative AI by illustrating that probabilistic rules could imitate aspects of human language (Ganguli et al., 2022). A related milestone in mid-20th-century thought was Alan Turing’s proposal of the imitation game (now known as the Turing test) in 1950. Turing suggested that if a machine’s textual responses could fool a human interrogator into thinking it was human, the machine could be considered intelligent. Although this idea did not describe a generative technique per se, it established a goal for conversational systems and spurred research into making machine text output more human-like. The Turing Test became a long-standing benchmark for conversational AI, influencing early chatbot development and evaluation (Gonçalves, 2023).
3.1 Rule-based Chatbots: ELIZA, PARRY and AIML
The 1960s and 1970s saw the creation of the first text-based chatbots, which were rule-based rather than statistical. A pivotal example was ELIZA, developed by Joseph Weizenbaum at MIT in 1966, often cited as the first publicly available chatbot program (Weizenbaum, 1966). It highlighted the limitations of pure pattern matching; as conversations strayed from its scripted patterns, ELIZA produced either repetitive or nonsensical responses. In 1972, psychiatrist Kenneth Colby introduced PARRY, a chatbot intentionally designed with a simulated personality (Labadze et al., 2023). While ELIZA played the role of a therapist, PARRY mimicked a patient—specifically, a paranoid schizophrenic persona. PARRY’s rules were crafted to exhibit paranoid thought patterns (e.g., suspicion, hostility), diverting the conversation when pressed and sometimes responding with seemingly illogical statements to reflect the paranoid mindset. These early chatbots, ELIZA and PARRY, were rule-based and domain-specific, yet they demonstrated the feasibility of conversational software and influenced many future projects.
Throughout the 1980s and 1990s, chatbot development continued with incremental improvements in pattern-matching techniques and knowledge encoding. An interesting 1983 system called Racter generated surreal pseudo-English prose using a mix of grammar rules and randomness (Adamopoulou and Moussiades, 2020). Racter even authored a short book, The Policeman’s Beard is Half Constructed (1984), composed entirely of its computer-generated writings. While largely nonsensical, Racter’s output showed that bots could create original sentences rather than merely reordering user inputs (Table 2).
Another line of development was Jabberwacky, begun in 1988 by Rollo Carpenter, which took a different approach: instead of explicit rules, it learned by interacting with users (Creswell et al., 2018). Its later incarnation, Cleverbot (2008), leveraged this data-driven approach, winning multiple Loebner Prizes (an annual Turing Test competition started in 1991) by engaging users with more natural, less scripted replies (Joo et al., 2021). The success of Jabberwacky/Cleverbot hinted at the power of corpus-based learning: a chatbot could improve by mining large conversation logs, foreshadowing the data-driven techniques of modern AI. One of the most influential early frameworks was the Artificial Linguistic Internet Computer Entity (ALICE), created by Richard Wallace in 1995 (Labadze et al., 2023). ALICE was a rule-based chatbot like its predecessors but far more advanced in its pattern matching. It introduced a standardized structured scripting language called Artificial Intelligence Markup Language (AIML) for encoding chatbot responses (Eltahir et al., 2022). AIML allowed developers to define categories of user input patterns (using wildcard matching, synonyms, etc.) and to specify templated replies.
Table 2. Timeline of key milestones in text-based generative AI (1906–2023).
3.2 The shift to machine learning in the 2000s
By the early 2000s, machine learning (ML) techniques began transforming conversational AI. Researchers shifted from relying solely on manual rules to training models on data, enabling systems to learn how to respond. Several factors drove this shift: the availability of large digital text corpora (e.g., the expanding web), improvements in computing power, and breakthroughs in statistical learning algorithms (Fagyal, 2022). A major leap occurred with the rise of deep learning (multilayer neural networks) in the mid-2000s, providing powerful new methods for pattern recognition in text, speech, and other modalities. In 2001, a popular commercial system called SmarterChild, a chatbot deployed on AOL and MSN instant messengers, showcased this potential (Ashfaque et al., 2020). SmarterChild could fetch facts (news, weather, stock quotes) and engage in simple banter by connecting to databases and web APIs. While much of its behavior was pre-scripted, SmarterChild demonstrated how a chatbot could integrate with real-world data sources and serve as a useful assistant on messaging platforms, reaching millions of users.
This development foreshadowed modern virtual assistants like Siri and Alexa, which combine programmed capabilities with online information retrieval. By the early 2010s, researchers began applying recurrent neural networks (RNNs), particularly long short-term memory (LSTM) networks, to model entire sentences and dialogues. For instance, in 2014, Sutskever, Vinyals, and Le at Google demonstrated a sequence-to-sequence neural network capable of taking an input sentence and producing a reply, effectively learning a conversation mapping from data (Yousuf et al., 2021). In 2015, Vinyals and Le published “A Neural Conversational Model,” one of the first end-to-end trained chatbots that learned to respond in a Twitter chat style by training on a large collection of dialogue-like exchanges. Although these early neural chatbots were innovative, they were also rudimentary; they tended to produce very generic answers (“I don’t know” or “OK”) and lost coherence over longer conversations due to limitations in sequence models and training data. Nonetheless, they demonstrated that with sufficient data, neural networks could learn dialogue patterns without explicit rules, marking a significant departure from the rigid AIML approach (Chen et al., 2017).
An important case study in applying ML to conversation was IBM’s Watson (Maher, 2020). While not a chatbot for open-ended chat, Watson was a question-answering system that famously won the quiz show Jeopardy in 2011, showcasing its ability to parse natural language questions and retrieve accurate answers. Watson’s DeepQA architecture combined various techniques (parsing, search, knowledge bases, and machine learning for ranking answers). Around the same time, voice-based digital assistants emerged: Apple’s Siri (2011), Google Now (2012), Microsoft Cortana (2014), and Amazon Alexa (2014) all entered the market (Mostafa et al., 2024; Katsarou et al., 2023; Paul, 2017). These assistants primarily utilized a pipeline of automatic speech recognition, intent classification, and scripted response generation, but they increasingly integrated ML for intent prediction and personalization. The Defense Advanced Research Projects Agency (DARPA) had previously funded an ambitious project called CALO (Cognitive Assistant that Learns and Organizes), which contributed technology that ultimately led to Siri (Tur et al., 2008; Krotkov and Blitch, 1999).
3.3 Emergence of modern generative models: VAEs, GANs, and transformers
While early chatbot research focused on dialogue rules and statistical responses, the broader field of generative AI underwent a revolution in the 2010s with the introduction of new model architectures. Two influential classes of generative models emerged in the mid-2010s, VAEs and GANs (Singh and Ogunfunmi, 2021). Introduced in 2013, VAEs provided a probabilistic framework for generating new data similar to a training set (Chen et al., 2024). A VAE consists of an encoder network that learns to map inputs into a latent vector representation—a compressed “idea” of the data—and a decoder that reconstructs data from this latent space. By sampling from the latent space, VAEs can produce entirely new outputs, such as new images that resemble those in the training set or, in principle, new text sequences.
GANs, proposed in 2016, took a different approach by pitting two neural networks against each other: a generator that creates fake data and a discriminator that distinguishes fakes from real data (Hinz et al., 2016). Through this adversarial training, the generator learns to produce highly realistic outputs that can fool the discriminator. GANs achieved remarkable results in generating images (e.g., photorealistic human faces) and became a cornerstone of image-based generative AI. Although VAEs and GANs have been applied with some success in text generation (for example, to generate sentences or poetry), generating text proved more challenging due to its discrete and sequential nature. Instead, the most impactful development for text generative modeling turned out to be the advancement of large language models (LLMs) based on the Transformer architecture.
The Transformer is a deep neural network architecture designed specifically for sequence modeling, utilizing a mechanism called self-attention to handle long-range dependencies in text (Lin et al., 2022). The practical significance of the Transformer architecture became evident with its adoption in large-scale models. One early application was in machine translation, exemplified by Google’s Transformer-based translation system in 2017 (Rahali and Akhloufi, 2023). Researchers soon realized that training Transformers on massive text corpora to predict missing words or the next word could yield models with an impressive grasp of language. These are known as language models, and when scaled up, they began to exhibit emergent abilities such as generating coherent paragraphs, carrying on dialogues, and answering questions without task-specific programming. The "Attention is All You Need" paper introduced the core architecture, and subsequent work by OpenAI and others demonstrated that simply increasing the model’s size (in terms of parameters) and training data led to qualitative leaps in performance (Vaswani et al., 2017). For instance, research on scaling laws found that larger models trained on more data continue to improve in a predictable log-linear fashion on language tasks. This insight triggered a “race” in the late 2010s to build bigger and better Transformer-based language models, setting the stage for the GPT series (Kaplan and Haenlein, 2020).
3.4 Transformer-based language models: The GPT series
OpenAI’s generative pre-trained transformer (GPT) family exemplifies the evolution of transformer-based text models. These models share a common approach: a Transformer decoder network trained on a vast corpus of text in an unsupervised manner, primarily by predicting the next token. The first model, GPT-1, was introduced in 2018 with 117 million parameters. GPT-1 demonstrated that a generic language model pre-trained on unlabeled text could be fine-tuned for specific tasks, such as question answering or sentiment analysis, using relatively little labeled data—a technique known as transfer learning (Zhuang et al., 2021). This marked a significant departure from the traditional practice of training task-specific models from scratch. GPT-1’s architecture already incorporated the hallmarks of its successors, including multi-layer self-attention blocks that enable it to consider the context of sentences when generating or interpreting text.
Building on this foundation, GPT-2 was released in 2019, significantly larger at 1.5 billion parameters. GPT-2 exhibited a quantum leap in text generation quality, producing startlingly coherent and contextually relevant paragraphs of fiction or news-like text in response to prompts (Tabassum et al., 2025; Raiaan et al., 2024). OpenAI famously withheld the full GPT-2 model initially due to concerns it could be misused to generate disinformation or spam at scale. After a staged release and the absence of immediate crises, GPT-2 was eventually made public, underscoring the ethical questions surrounding powerful generative text models (Kukreja et al., 2024).
The next major milestone, GPT-3, arrived in 2020 with 175 billion parameters—more than two orders of magnitude larger than GPT-1. GPT-3’s size and training on roughly 500 billion tokens of internet text endowed it with remarkable capabilities that surprised even experts (Annepaka and Pakray, 2025). Without any fine-tuning, GPT-3 could perform tasks such as answering trivia questions, composing essays, summarizing texts, or writing code, simply by being prompted in plain English—a phenomenon dubbed few-shot learning or in-context learning. For example, given a prompt like “Translate the following English sentence to French: . . . ” GPT-3 would produce a reasonable translation, even though it was never explicitly trained on a supervised translation dataset. This versatility indicated that GPT-3 had learned a broad array of linguistic and world knowledge during pre-training. Its release was pivotal, as developers began integrating GPT-3 (accessible via OpenAI’s API) into numerous applications, ranging from writing assistants to customer service chatbots. It became clear that LLMs could be treated as general-purpose language generators and conversational agents. As one report noted, GPT-3’s debut marked a transformative impact, demonstrating that AI could produce human-like text for a wide range of practical tasks (Suhaili et al., 2021).
Despite their prowess, GPT-3 and similar models have notable weaknesses: they can generate factually incorrect statements ("hallucinations"), reflect biases present in the training data, and follow harmful instructions if prompted maliciously (Hua et al., 2024). This has led to efforts aimed at aligning LLMs with human values and user intent. OpenAI's solution was to fine-tune the models using human feedback, resulting in InstructGPT and later ChatGPT. The technique, Reinforcement Learning from Human Feedback (RLHF), involves first collecting example conversations and preferences from human annotators, then training the model to favor responses that humans rate as helpful and harmless (Retzlaff et al., 2024). Specifically, OpenAI's trainers generated demonstration dialogues and comparisons of model responses, trained a reward model to predict which responses humans would prefer, and then optimized the language model using a reinforcement learning algorithm (proximal policy optimization) to produce responses that maximize this reward. Through RLHF, OpenAI fine-tuned a version of GPT-3 (the 175B model) into GPT-3.5, the model that powers ChatGPT, which was initially released as a free research preview in November 2022 (Huang and Huang, 2024). According to OpenAI, ChatGPT's training adhered to the InstructGPT methodology, with human AI trainers simulating conversations and providing feedback to iteratively refine the model. The result is a system that is significantly better at following user instructions, refusing inappropriate requests, and maintaining conversational context compared to the raw GPT-3.
ChatGPT quickly became a global phenomenon. For many users, it was their first encounter with an AI capable of carrying on open-ended conversations, explaining almost any topic, and producing essays or code on demand, all with a fluidity that passes the Turing-like sniff test in most cases. Within months, ChatGPT reached 100 million users, making it one of the fastest-adopted technologies ever. Its underlying model (GPT-3.5 and later GPT-4) is still fundamentally a text predictor, but the conversational fine-tuning and sheer scale of training provide it with an uncanny simulacrum of understanding (Proctor et al., 2020).
Technically, ChatGPT maintains a conversation by taking the entire chat history as input for each response, utilizing the Transformer’s capacity to attend to the prior dialogue context. The model does not truly “remember” in a human sense; however, with enough layers and parameters, it can implicitly encode conversational state and produce contextually consistent answers. In March 2023, OpenAI announced GPT-4, a larger and more advanced model (exact details such as parameter count were not publicly disclosed, but estimates range from a few hundred billion to over a trillion parameters) (Tu et al., 2024). GPT-4 is multimodal, accepting image inputs in addition to text. It exhibits strong performance on professional and academic benchmarks, passing many standardized exams (like the bar exam) at levels close to the top human percentiles. OpenAI reported that they spent over six months iteratively aligning GPT-4 using lessons from adversarial testing and user feedback, making it their most accurate and steerable model to date. GPT-4’s improvements are particularly notable in complex reasoning, creativity, and following nuanced instructions. However, like its predecessors, it is not infallible; it can still err or produce biased content, and OpenAI continues to refine its safety through techniques like RLHF and system behavior constraints (Katz et al., 2024).
In parallel to OpenAI’s work, other tech giants and research groups have developed their own large transformer-based language models. For instance, Google’s LaMDA (Language Model for Dialogue Applications) was unveiled in 2021 as a family of transformer-based dialogue models ranging from 2 billion to 137 billion parameters. LaMDA was trained on an enormous corpus of 1.56 trillion words from public dialogues and web documents, specifically designed for conversational use (Zhang et al., 2023). It incorporates modules for safety, to filter out inappropriate responses, and grounding, to utilize external knowledge sources, enabling it to produce multi-turn dialogue that is often deeply context-aware.
In early 2023, Google launched Bard, a conversational AI service built on a fine-tuned version of LaMDA. Bard's rollout was cautious, beginning with a limited waitlist, and initial feedback on its performance was mixed, prompting Google to rapidly update the model to enhance its accuracy, coding ability, and multilingual support. By mid-2023, Bard was available in 180 countries and integrated capabilities like code generation and answer justification, reflecting a fast-paced, iterative deployment (Pellas, 2025).
Meanwhile, companies like Meta (formerly Facebook) and Anthropic have also entered the fray: Meta released LLaMA (2023), a suite of open-source LLMs (ranging from 7 billion to 65 billion parameters) for research, while Anthropic created Claude, an AI assistant focused on being harmless and helpful, trained using a technique called “Constitutional AI” (Sicari et al., 2025). The competition and diversity of approaches—such as OpenAI’s GPT series, Google’s LaMDA/Bard, and Anthropic’s Claude—have accelerated progress in generative text models, rapidly pushing them from research labs into mainstream products.
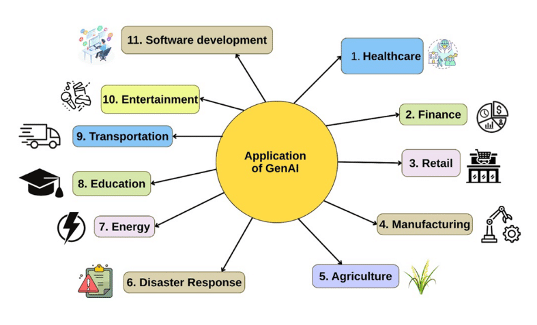
Generative AI is now utilized across various domains. Figure 1 illustrates the broad spectrum of generative AI applications across eleven key sectors, including healthcare, finance, manufacturing, education, and disaster response. GenerativeAI enhances efficiency, creativity, and decision-making by generating context-specific content, simulating complex scenarios, and optimizing system operations. Its growing integration across industries highlights its transformative potential to reshape traditional workflows, accelerate innovation, and address global challenges through intelligent automation and human-AI collaboration.
3.5 Open-source models and democratization of generative AI
An important development in recent years is the democratization of generative AI through open-source initiatives. Initially, the most powerful language models were proprietary, accessible only via APIs or not at all due to the immense resources required to train them. However, the AI community has made concerted efforts to create and release advanced models openly. A prime example is the BLOOM model (2022), a 176-billion-parameter multilingual language model developed by the BigScience project, a consortium of over 1,000 researchers from around the globe. BLOOM was trained on 46 natural languages and 13 programming languages and was released under an open license, allowing anyone to download and experiment with it (Storey et al., 2025). Around the same time, Meta released the OPT family (up to 175B parameters) and later the LLaMA models (2023) to researchers, providing detailed documentation of their training data and techniques. Although the largest models still require significant hardware to run, these open releases sparked a wave of innovation: researchers and hobbyists fine-tuned smaller versions that could run on a single GPU or even a laptop. For instance, after LLaMA's weights leaked online, community developers created Alpaca, Vicuna, and other variants by fine-tuning LLaMA on instructional data, achieving ChatGPT-like behavior on consumer hardware at a fraction of the model size (Ray, 2023). This trend continued with projects like StableLM (stability AI's open LLM), Falcon (TII UAE's 40B and 180B parameter open models), and Mistral (a 7B French model with strong performance). By late 2023, users could choose from dozens of open-source LLMs covering various model sizes and languages.
The impact of open-source generative models is significant. It lowers the barrier to entry for research and application development, as organizations no longer need tens of millions of dollars to train a cutting-edge model; they can fine-tune an existing open model with much less computational power. It also allows for greater transparency and scrutiny, enabling researchers to examine the training data and weights to identify biases or weaknesses, which is often not possible with closed models.
Moreover, community-driven improvements—such as optimizing model architectures for efficiency or developing new fine-tuning techniques—can propagate quickly when the models are openly available. In essence, the availability of open LLMs has "democratized" access to generative AI, ensuring it is not solely controlled by a few large tech companies (Zafar et al., 2024). However, this also means that the risks associated with generative text (e.g., misuse for spam or deepfake text) are not limited to those who have API keys; anyone can deploy an open-source model. This has led to calls for responsible use and possibly regulation, even in the open-source sphere, to prevent the abuse of powerful AI models.
4. Societal integration of generative AI
4.1 Transforming collaboration, creativity, and discovery
The evolving synergy between humans and generative AI is charting new territories in collaborative intelligence. This partnership enhances human cognitive processes by leveraging AI for advanced analytics, predictive modeling, and simulation (Fahimi et al., 2021). The objective is to optimize the collective cognitive output of human-AI teams, where algorithms balance performance gains against interaction costs. Seamless workflow integration is achieved through adaptive mechanisms like reinforcement learning, allowing AI systems to dynamically align with user needs and evolving task requirements. This transition transforms AI from a passive tool into an active creative and analytical partner (Reddy, 2024). By synthesizing vast datasets into actionable insights, these systems improve human decision-making, particularly in areas where data complexity surpasses human processing abilities.
This transformative potential extends deeply into creative and scientific domains. In generative design, AI utilizes sophisticated optimization algorithms to navigate multidimensional design spaces, identifying novel solutions that balance criteria such as functionality, sustainability, and aesthetics (Castro et al., 2021). In scientific research, AI's ability to analyze extensive literature and data facilitates the generation of novel, testable hypotheses. This analytical power can uncover subtle patterns and previously unseen correlations, thereby accelerating the cycle of scientific discovery (Wang et al., 2023). Furthermore, AI can assist in designing optimal experimental protocols to validate these hypotheses, maximizing the efficiency and potential impact of the research.
4.2 Societal preparedness for an AI-augmented future
As generative AI becomes woven into the fabric of daily life, preparing society requires a multifaceted approach grounded in ethical, educational, and infrastructural foresight. Formulating robust ethical and policy frameworks is essential for navigating the complexities of AI deployment, ensuring that technologies serve the common good while safeguarding individual rights (Chan, 2023). A primary concern is algorithmic fairness, which involves developing models to quantify and mitigate bias, thereby preventing disparate outcomes across demographic groups. Concurrently, fostering widespread AI literacy through updated educational curricula and public awareness campaigns is pivotal. These educational initiatives aim to equip citizens with the critical understanding needed to interact with AI systems effectively and ethically (Ng et al., 2021). Finally, ensuring equitable access to the benefits of AI necessitates significant investment in inclusive technological infrastructure, guided by optimization models that maximize public access and participation.
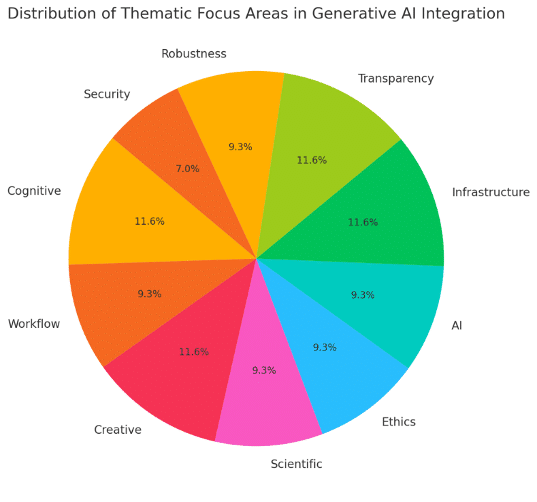
Figure 2 illustrates the distribution of thematic focus areas in the societal integration of generative AI, based on a synthesis of the literature. Each segment represents the relative emphasis placed on a particular topic, measured by the density of unique keywords identified in the thematic summaries. Notably, cognitive augmentation, workflow integration, and ethics and policy occupy prominent portions of the chart, reflecting strong scholarly and practical interest in how generative AI enhances human capability, integrates into decision-making workflows, and raises ethical governance challenges. Meanwhile, areas such as infrastructure access and security and ethical alignment receive focused but equally significant attention, particularly in discussions of equitable AI deployment and the safeguarding of sensitive applications. This distribution highlights the multifaceted nature of generative AI's societal impact and underscores the need for interdisciplinary approaches to ensure responsible adoption.
4.3 Overcoming advanced challenges in generative AI
The increasing sophistication of generative models presents complex challenges related to transparency, robustness, security, and ethical alignment. Addressing these issues is essential for the responsible advancement and integration of AI technologies.
A significant barrier to the adoption of complex AI is its "black box" nature, which renders the internal decision-making process opaque. Therefore, enhancing transparency is a critical area of research for building trust and accountability (Gupta et al., 2024). Two principal strategies have emerged to tackle this opacity: the development of inherently interpretable models and the application of post-hoc interpretability techniques, as summarized in Table 3.
Table 3. Approaches to AI transparency.
The reliability of AI systems is crucial in critical applications where failure can have significant consequences. Robustness can be enhanced through adversarial training, a process that exposes a model to carefully crafted inputs designed to induce errors. This min-max optimization approach improves the model's resilience against malicious perturbations it may encounter during deployment (Qiao et al., 2018). System reliability is further strengthened by incorporating fault-tolerant designs, such as component redundancy, which ensures operational continuity in the event of partial system failure. These architectural strategies are often complemented by real-time error detection and correction mechanisms that preserve data integrity throughout the AI's processing pipeline (Medjek et al., 2021).
In addition to robustness, the security and ethical alignment of generative AI require advanced strategies. Ethical decision-making frameworks can be integrated directly into an AI’s reward function, compelling the system to balance task utility with adherence to predefined ethical principles (Diro et al., 2025). To navigate complex ethical dilemmas with multiple competing values, multi-objective optimization can identify actions that represent a Pareto-optimal solution. Securing these systems necessitates advanced cryptographic protocols. For instance, homomorphic encryption enables computation on encrypted data, preserving privacy in sensitive applications like healthcare (Rahman et al., 2020). Similarly, secure multi-party computation (SMPC) allows for collaborative AI model training across different organizations without requiring any party to expose its private data, facilitating secure and cooperative innovation (Diro et al., 2025).
5. next-generation Generative Models
The advancement and exploration of next-generation generative models, as shown in Figure 3, are pivotal in driving the future of artificial intelligence. This marks a significant shift from classical computational approaches to more complex, quantum-enhanced methodologies. This evolution is characterized by the adoption of quantum computing paradigms, sophisticated meta-learning techniques, and the fusion of knowledge from disparate domains to enhance the capabilities of generative AI.
5.1 Quantum integration in generative AI (2018–present)
The integration of quantum computing with generative models began in 2018 when Lloyd and Weedbrook introduced quantum generative adversarial networks (QGANs) (Lloyd and Weedbrook, 2018). QGANs extend classical GAN frameworks into the quantum domain by representing the generator and discriminator components as quantum circuits. These systems utilize quantum superposition and entanglement to optimize value functions over quantum states, enabling the modeling of intricate data distributions with quantum efficiency.
Between 2019 and 2020, research expanded to include variational quantum circuits (VQCs), which combine parameterized quantum gates with classical optimization to generate quantum data (Chen et al., 2020; Dallaire-Demers and Killoran, 2018). These circuits support the minimization of state distance metrics, such as fidelity, to enhance generative accuracy. From 2021 onwards, the focus shifted to hybrid quantum-classical architectures, integrating quantum components with neural networks (Sun et al., 2021). These hybrid models allow classical data to be encoded into quantum states, processed through quantum operations, and then decoded into outputs. This fusion not only increases computational capacity but also enables novel applications in cryptography, drug discovery, and materials science.
5.2 Meta-learning and self-optimizing architectures (2016–present)
Meta-learning enables generative systems to adapt their learning strategies based on prior experience. A pivotal milestone occurred in 2016 with the introduction of model-agnostic meta-learning (MAML), which allows models to rapidly generalize to new tasks with minimal data (Mahmud and Lim, 2022). MAML adjusts parameters to maximize performance after only a few gradient updates, providing a generalizable and efficient training framework. In 2018, neural architecture search (NAS) emerged as a method for automating the discovery of model structures, optimizing architectural design spaces to enhance performance on validation tasks. This approach reduces manual model engineering and supports structural adaptability (Alotaibi and Ahmed, 2025; Yu et al., 2025).
Since 2019, advanced meta-learning techniques have incorporated reinforcement learning, evolutionary algorithms, and self-supervision. Reinforcement learning-based NAS treats architecture discovery as a sequential decision process; evolutionary methods iteratively refine model designs across generations; and unsupervised meta-learning employs self-generated tasks to adapt without labeled data. Together, these developments underpin generative systems that are increasingly capable of self-evolution and autonomous optimization.
5.3 Multi-modal generative models and cross-domain synergies (2017–present)
Generative AI has made substantial strides in integrating multiple data modalities—text, vision, and audio—into unified frameworks. In 2017, Pix2Pix and CycleGAN enabled image-to-image translation using conditional adversarial networks (Isola et al., 2017; Zhu et al., 2017). These models established early precedents for learning mappings between distinct visual domains, preserving content while transferring style. From 2018 to 2019, OpenAI introduced CLIP and DALL-E, further advancing the field of cross-modal generative learning. CLIP aligned text and images through contrastive learning, achieving robust zero-shot image classification. In contrast, DALL-E synthesized images from textual input, modeling the joint distribution of linguistic and visual tokens using a transformer-based architecture (Jamal et al., 2024).
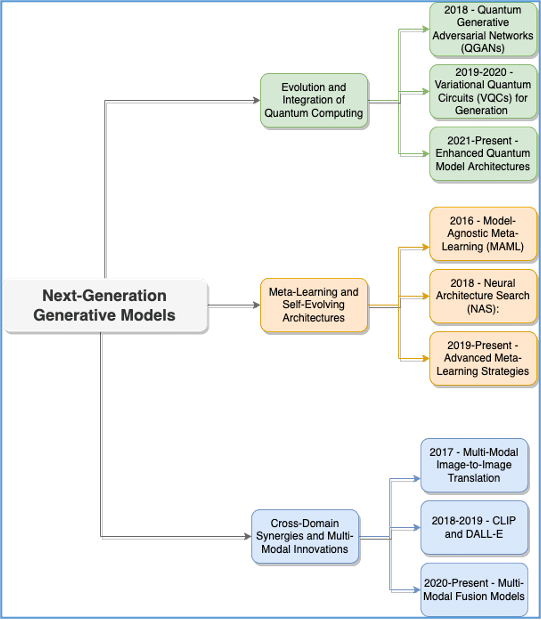
Since 2020, generative models have increasingly embraced multimodal fusion. This trend includes the development of architectures such as Google’s Multimodal Transformer and OpenAI’s GPT-3, which jointly process text, image, and audio data (Roumeliotis and Tselikas, 2023; Tsai et al., 2019). These systems translate between modalities, synthesize video content from scripts, and even reconstruct 3D scenes from textual descriptions. The mathematical frameworks supporting such systems incorporate encoding and decoding mechanisms across domains, marking a significant leap toward AI systems that mirror human-like perceptual and generative capabilities.
5.4 Cutting-edge research and uncharted territories
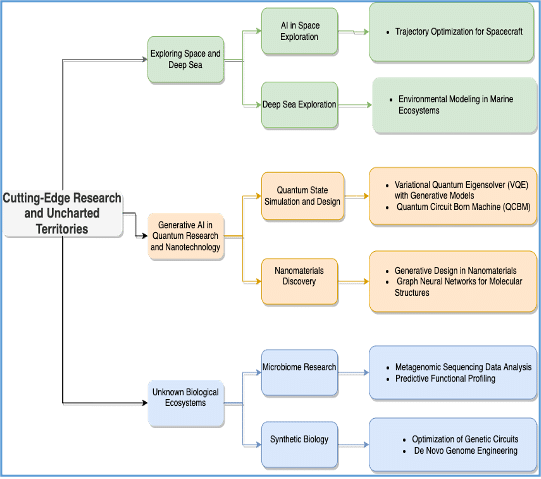
The frontiers of generative AI research are expanding into domains previously deemed inaccessible, ranging from the depths of the ocean to the vastness of space, as well as the intricate realms of quantum physics, nanotechnology, and complex biological ecosystems. In extreme environments such as space and the deep sea, generative models enhance exploration by simulating hazardous conditions, optimizing spacecraft trajectories, and predicting ecological impacts using data from sensors and satellites (Lyman et al., 2022). In quantum research, generative AI has played a significant role in simulating quantum states, with applications including the variational quantum eigensolver (VQE), which estimates molecular ground state energy, and quantum circuit born machines (QCBMs), which model quantum state distributions (Liu and Wang, 2018; Kandala et al., 2017). These tools provide unprecedented precision in understanding quantum behavior and material properties. In nanotechnology, generative design approaches facilitate the discovery and optimization of nanomaterials for specific applications, with graph neural networks central to predicting molecular interactions and material performance (Wang et al., 2020; Rodrigues, 2019). In the biological sciences, generative AI is revolutionizing microbiome research by analyzing metagenomics sequencing data to classify microbial taxa and predict ecological functions, thereby supporting conservation and public health strategies (Medina et al., 2022). It also advances synthetic biology through the optimization of genetic circuits and the engineering of entire genomes tailored for functions such as pollution reduction or renewable energy generation (Xiao et al., 2023). This multidisciplinary push into uncharted scientific territories underscores generative AI's growing role as an enabler of exploration, simulation, and discovery across the physical, molecular, and biological frontiers of human knowledge (Figure 4).
5.5 Deep theoretical enhancements in generative AI
The evolution of generative AI has been significantly enriched by theoretical frameworks that illuminate the underlying dynamics, statistical reasoning, and cognitive potential of these systems. From the perspective of complex systems and chaos theory, generative models are increasingly understood as high-dimensional dynamical systems, where small changes in parameters can lead to divergent training outcomes. Figure 5 presents a hierarchical taxonomy of advanced theoretical frameworks designed to enhance generative AI models. It organizes these improvements into three main pillars: complex systems and chaos theory, which leverages concepts like fractals for sophisticated data generation; probabilistic models and inference, which focuses on managing uncertainty through techniques like VAEs; and generative models as cognitive systems, which explores the integration of human-like memory, creativity, and interaction. This classification provides a clear roadmap for research directions aimed at developing more powerful and intelligent generative systems.
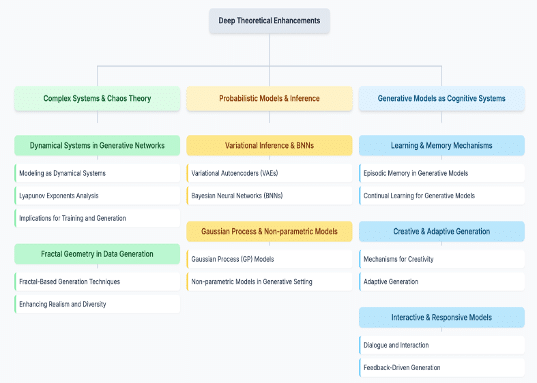
Concepts such as Lyapunov exponents are employed to assess model stability and guide convergence behavior (Roumeliotis and Tselikas, 2023; Gonog and Zhou, 2019). Concurrently, the integration of fractal geometry facilitates the generation of self-similar patterns and structures, enabling models to simulate the recursive complexity observed in natural environments (Tuncer et al., 2021). Probabilistic inference techniques have also played a pivotal role in advancing generative models. The VAEs utilize variational inference to approximate latent distributions, providing interpretable and controllable representations of data. Bayesian neural networks (BNNs) extend this approach by incorporating uncertainty into model weights, allowing predictions that reflect confidence intervals rather than just point estimates (Apellániz et al., 2024; Wu et al., 2022).
Non-parametric methods, such as Gaussian processes (GPs), offer flexible prior distributions over functions and support smooth interpolation and uncertainty modeling without relying on fixed architectures (Asso et al., 2021). Meanwhile, generative models have begun to incorporate cognitive-like abilities through memory-augmented architectures and continual learning strategies. Episodic memory mechanisms enable models to recall and apply relevant past outputs based on contextual prompts, while methods such as elastic weight consolidation (EWC) help preserve prior knowledge during incremental learning tasks (Fayyaz et al., 2022; Liu et al., 2019). These cognitive enhancements are further complemented by creative and adaptive capabilities, including mechanisms for conceptual blending and divergent thinking, as well as conditional and feedback-driven generation strategies that allow models to adapt to evolving inputs and environments (Anantrasirichai and Bull, 2022). Systems like GPT-3 exemplify these trends, responding dynamically to user input and refining outputs based on interactions, thereby blurring the lines between generative computation and human-like cognition (Lu et al., 2017). Collectively, these theoretical advancements form the intellectual foundation of next-generation generative AI, equipping models with the capacity to reason, adapt, and interact in increasingly sophisticated and human-aligned ways.
6. Foreseeing the future: Trends, challenges, and ethical imperatives
6.1 Human–AI co-evolution: A trajectory of cognitive convergence
The integration of GenAI into human cognitive and social systems reflects an ongoing co-evolution rather than a one-sided enhancement. Advances in brain-computer interfaces, neuro-adaptive systems, and context-aware technologies are progressively blurring the boundary between artificial and biological intelligence (Buthut et al., 2024). In emerging concepts like the “hybrid mind,” AI merges seamlessly with human cognitive processes, positioning itself not only as a tool but as a cognitive collaborator that works alongside humans in shared tasks (Ziegler and Donkers, 2024). This convergence can be conceptualized as a synergistic human-AI system in which the total cognitive capacity exceeds the simple sum of each contributor’s intelligence. In such a system, AI algorithms increasingly shape human decision-making, memory, and perception, while human values, context, and feedback, in turn, influence AI development and behavior. Modeling these dynamics is complex, and researchers emphasize the need for predictive frameworks and anticipatory governance approaches to forecast and guide future human-AI ecosystems (Cugurullo and Xu, 2025). Developing such models and governance mechanisms will be essential for designing adaptive policies that keep pace with human-AI co-evolution.
6.2 Expanding roles of GenAI: Creative, industrial, and civic transformation
GenAI’s capabilities continue to expand across a wide range of sectors, from creative industries to critical infrastructure and public services. In creative domains, generative AI is increasingly integrated with virtual and augmented reality to produce personalized artistic experiences and novel forms of interactive media. The advent of AI-generated art has expanded the boundaries of creative expression while sparking debates about authorship, originality, and the very nature of art. On one hand, AI tools serve as creative partners, democratizing content creation and enabling individuals without formal training to produce sophisticated works. On the other hand, these developments challenge traditional notions of creativity and artistic merit, raising concerns about the devaluation of human artistry and cultural heritage in an era of machine-generated expression (Hall and Schofield, 2025). Questions such as “Who is the author of AI-generated content?” and “What constitutes artistic value when an algorithm contributes to the work?” remain unsettled, illustrating the disruptive impact of GenAI on cultural norms. In applied contexts, GenAI is reshaping operations in healthcare, education, transportation, industry, urban planning, and more. For example,
- Healthcare: Generative models can simulate virtual patient populations and design personalized treatments. By generating realistic synthetic patient data, GenAI helps predict patient responses and treatment outcomes across diverse genetic and demographic profiles, thereby advancing precision medicine and tailored therapies (Ghebrehiwet et al., 2024). These models are employed to discover drug candidates, recommend treatment plans, and even synthesize medical images for training and diagnostic purposes.
- Education: Intelligent tutoring systems powered by GenAI personalize instruction and create immersive learning environments. For instance, AI can generate custom lesson content, practice problems, or even virtual tutors tailored to a student’s learning style and pace. Such systems provide real-time feedback and adaptive learning pathways, enhancing engagement and improving learning outcomes.
- Transport and industry: In manufacturing and transportation, GenAI contributes to the development of digital twins, predictive maintenance, and smart optimization systems. Digital twin simulations create virtual replicas of physical assets or systems, leveraging generative AI to run real-time scenarios for machinery and infrastructure, which improves fault diagnosis and maintenance scheduling (Mikołajewska et al., 2025). Similarly, AI-driven traffic models can generate and evaluate traffic management strategies (e.g., signal timing or routing adjustments) to reduce congestion and emissions. These applications support sustainability and efficiency goals in smart cities and Industry 4.0 environments.
- Cybersecurity: Generative models are emerging as tools for both offense and defense in cybersecurity. On the defensive side, AI can generate realistic attack scenarios to train and strengthen intrusion detection systems and create honeypots for threat analysis. Research has shown that GANs can simulate novel cyber-attacks or variations of malware, helping security teams anticipate and patch vulnerabilities. Conversely, these same techniques highlight the risks of adversaries using GenAI to craft highly evasive malware or phishing content. For example, one study demonstrated a GAN that generated adversarial network traffic capable of fooling multiple intrusion detection algorithms by producing new variations of attacks (Chowdhary et al., 2023). This dual-use nature of GenAI in cybersecurity underscores the need for robust safeguards (Ahmadi, 2025; Sultana, 2025).
- Urban planning: AI-enhanced simulations are increasingly informing policy decisions regarding energy use, waste management, disaster response, and infrastructure resilience in cities. Large-scale “city brain” platforms have been deployed that utilize GenAI (including LLMs) to integrate data across transport, public safety, utilities, and environmental monitoring. These systems can generate models of urban futures, projecting the impacts of new transportation policies or climate adaptation measures that city planners and policymakers can use to evaluate options (Cugurullo and Xu, 2025). By exploring numerous what-if scenarios (such as the effects of a new public transit line or changes in zoning laws), GenAI assists in designing urban environments that are more efficient, sustainable, and responsive to citizens’ needs. Such applications illustrate GenAI’s potential to serve as a generative infrastructure for innovation, problem-solving, and service delivery. However, as GenAI-driven systems become more embedded in daily life, their scale and influence demand correspondingly robust oversight.
6.3 Ethical and governance challenges: GenAI-augmented society
As GenAI systems increase in autonomy and societal presence, the ethical implications of their deployment grow more urgent. Key concerns include transparency (making AI decision processes understandable), accountability (assigning responsibility for AI-driven outcomes), bias mitigation (preventing discrimination), and the equitable distribution of AI-generated benefits. In many domains, unregulated GenAI could inadvertently perpetuate social and algorithmic biases or make opaque decisions with far-reaching impacts. For instance, if a financial AI system denies loans or if an AI medical diagnostic system makes a recommendation, stakeholders need transparency regarding how those decisions were reached and the ability to hold someone accountable for errors or biases. Indeed, as AI models become more complex and data-driven, their decision-making processes can appear as “black boxes,” raising the risk of biased or unexplainable outcomes. This lack of transparency, coupled with the potential for AI systems to cause unintended harm or infringe on rights, has led to widespread calls for stronger accountability and oversight in AI governance (Cheong, 2024). In high-stakes fields like healthcare and finance, explainability and reliability are essential for building trust. Experts note that explainable AI (XAI) can help make AI-driven decisions more transparent, reliable, and ethically compliant, which is vital for user and public acceptance in these fields (Mienye et al., 2024). If doctors, patients, bankers, or customers cannot understand or trust an AI’s recommendations, they will justifiably resist its use. Similarly, in creative and policy-related contexts, questions about authorship, intent, and moral agency for AI-generated content remain unresolved. AI systems, lacking consciousness or moral awareness, cannot yet be held to the same standards of intent or responsibility as humans, complicating issues of accountability when, for example, an AI policy advisor gives bad advice or an AI-created artwork infringes on someone’s rights. Scholars argue that because current AIs do not possess autonomous moral agency, assigning them moral responsibility (or legal authorship) is inappropriate; effectively, accountability in these cases must lie with the human developers, users, or regulators rather than the AI itself (Tang, 2024). Addressing these ambiguities will require new legal definitions (e.g., around intellectual property or liability) and ethical guidelines.
Establishing comprehensive ethical frameworks that prioritize human welfare and align with democratic values will be essential for responsible GenAI development. Such frameworks should be accompanied by international governance standards, multi-stakeholder policy processes, and public education initiatives. There is already movement in this direction at the global level; for example, organizations like the OECD and UNESCO have issued guidelines and recommendations for ethical AI, emphasizing principles such as fairness, transparency, and human rights (Cugurullo and Xu, 2025; Buthut et al., 2024). Likewise, policymakers are exploring participatory approaches to AI governance, involving a broad range of stakeholders (including citizens, domain experts, and industry) in the development of regulations and norms. This is crucial to ensure that GenAI systems augment society in ways that reflect collective values and avoid marginalizing any group. Technical strategies should also be integrated into AI development cycles to embed ethics by design. Approaches like interpretable and auditable modeling, bias audits, value-sensitive design (incorporating human values into the design process), and reinforcement learning from human feedback (to align AI behavior with human preferences and norms) are all being explored as means to make AI systems more aligned with societal expectations. By combining such technical safeguards with sound policy, we can better ensure that GenAI remains beneficial and under meaningful human control.
The future of GenAI is not solely a matter of engineering innovation; it is a societal project that requires inclusive dialogue, anticipatory regulation, and sustained ethical foresight. By proactively addressing the challenges of transparency, accountability, bias, and human agency, we can guide GenAI toward outcomes that enrich human capabilities and uphold human values. Through international collaboration, adaptive governance, and an emphasis on human-centered design, GenAI can become a catalyst not only for technological progress but also for a more equitable and sustainable civilization.
7. Conclusions
Generative AI represents a transformative shift in human progress, with immense potential to enhance human intelligence, revolutionize industries, and explore new frontiers in science and creativity. However, this advancement brings significant ethical, social, and governance challenges that require a collective and proactive response. To ensure that AI enhances rather than diminishes the human experience, its development must align with values of equity, transparency, and sustainability. A globally coordinated effort—rooted in education, inclusive dialogue, and robust policy frameworks—is essential to guide this evolution responsibly. As we move forward, integrating AI into society should be viewed not merely as a technological milestone but as a deeply human journey toward a more just, empowered, and interconnected future.
Acknowledgements
The authors gratefully acknowledge the academic environments, institutional support, and access to research tools provided by their respective institutions—University of South Australia, Flinders University, Bangladesh Agricultural University, and the World University of Bangladesh. Although this research received no external funding, it was enriched by scholarly discussions, peer feedback, and critical insights from reviewers and colleagues that helped strengthen the manuscript.
Funding information
This research was conducted without the support of any specific grant from public, commercial, or not-for-profit funding agencies.
Ethical approval statement
No ethical approval was required to conduct the study.
Data availability
All data supporting the findings of this study are derived from publicly accessible sources and are fully presented within the article.
Informed consent statement
Not applicable.
Conflict of interest
The authors declare no conflict of interest.
Authors’ contribution
Conceptualization and framework design: Abdullahi Chowdhury and Adyan Chowdhury; literature review and historical analysis: Nabila Hoque and Moriwam; Mathematical modeling and theoretical enhancements: Abdullahi Chowdhury and Musfera Jahan; Manuscript first draft and review: Abdullahi Chowdhury and Adyan Chowdhury. All authors critically reviewed the manuscript and agreed to submit final version of the manuscript.
